> For the complete documentation index, see [llms.txt](https://docs.tibero.com/prosync/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.tibero.com/prosync/4.5_manual/administration/apply/apply-process.md).
# Apply Process
Apply 프로세스에 대하여 설명한다.
## Process 설명
Apply 프로세스는 [제품 설계](/prosync/4.5_manual/introduction/architecture.md)에서도 언급했듯이 ***Chunk*** 단위로 레코드를 전달받고 해당 레코드를 트랜잭션별로 모아준다. 트랜잭션에 `Commit` 이 오면 해당 트랜잭션은 실제 반영 단계에 들어가 대상이 되는 데이터베이스로 반영된다.
본 장에서는, 실제 apply 프로세스의 구조를 상세히 설명한다.
***
## Threads
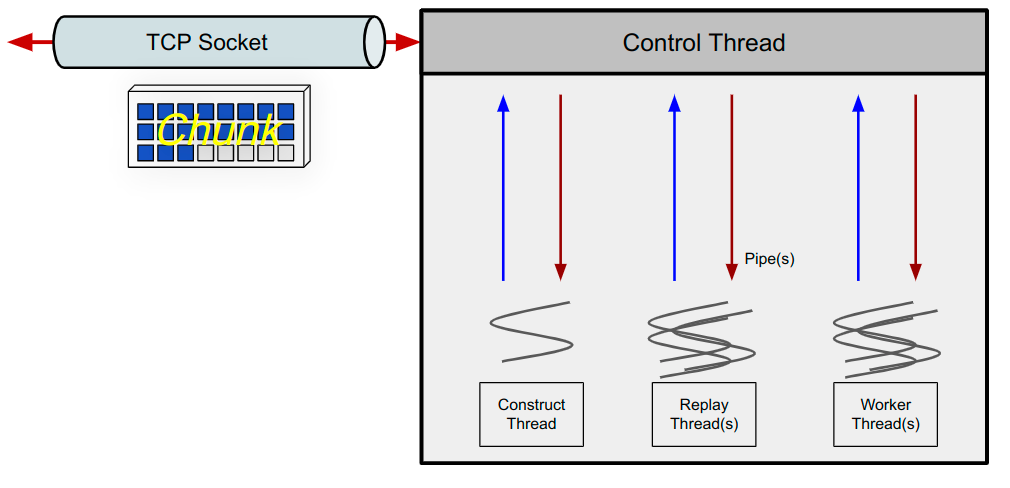
그림 1. Apply Process Architecture
Apply 프로세스는 위와 같은 구조를 가지고 있다. 앞서 [제품 설계](/prosync/4.5_manual/introduction/architecture.md#inter-processes-threads-communication) 에서 ProSync의 기본 Thread 구조를 언급한 바 있는데, Apply 도 마찬가지로 Main 이 되는 Control Thread 가 있고 이외에 Worker Thread 들이 Control Thread 하위 계층에 구성되어 있다.
동기화에 필요한 Thread는 Construct Thread 와 Replay Thread 로 크게 두 가지로, 나머지는 모두 Worker Thread 로 구분 된다.
{% hint style="info" %}
**참고**
Worker Thread는 종류가 많은 관계로 하단에 간단히 언급한다.
{% endhint %}
### Control Thread
Control Thread는 다른 프로세스와 마찬가지로 모든 통신과 관련된 `Multiplexing I/O` 를 담당한다. 리눅스에선 `epoll` 을 사용하며, 플랫폼 별로 `k-queue` 나 `pollset` 등 각 운영체제에 알맞은 Mux I/O 기능을 사용하도록 설계되어있다.
### Construct Thread
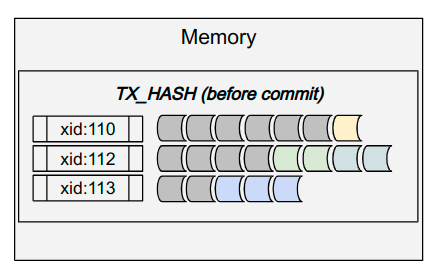
Construct Thread는 ***Chunk*** 로 들어오는 레코드 데이터들에 대해 `트랜잭션`으로 재조립한다. Construct 라는 말의 의미는 `트랜잭션` 을 다시 조립(**Construct**) 하기 때문에 사용된다고 생각하면 된다.
각 `레코드` 에는 본인이 속한 `트랜잭션` 을 구분할 수 있는 일종의 `key` 값이 존재하는데, 이게 `트랜잭션` 의 ID 일명 (`xid`) 라고 불린다.
Construct 는 `레코드` 의 `xid` 값을 보고 `트랜잭션` 별로 재조립한다.
그림 2. Construct의 트랜잭션 Hash
{% hint style="info" %}
**참고**
**Construct의 이력 정보 관리**
Construct는 `레코드` 별로 어떤 `redo` 로그 파일에서 나온 건지에 해당하는 `로그 시퀀스` 정보와 해당 로그 파일의 몇 번째 `레코드` 에 해당하는 지에 대한 정보(`wrap#` )를 메모리에 계속 저장하게 된다.
`redo` 로그는 주기적으로 `로그 스위치` 가 일어나고, 이 때마다 `로그 시퀀스` 값이 1개씩 올라가며 새로운 로그파일에 `레코드` 를 작성하게 되는데, 이 때마다 메모리에 들고 있던 `레코드` 정보 및 이력 정보(`로그 시퀀스` , `wrap#` ) 가 물리 디스크 및 데이터베이스에 저장된다.
{% endhint %}
### Replay Thread
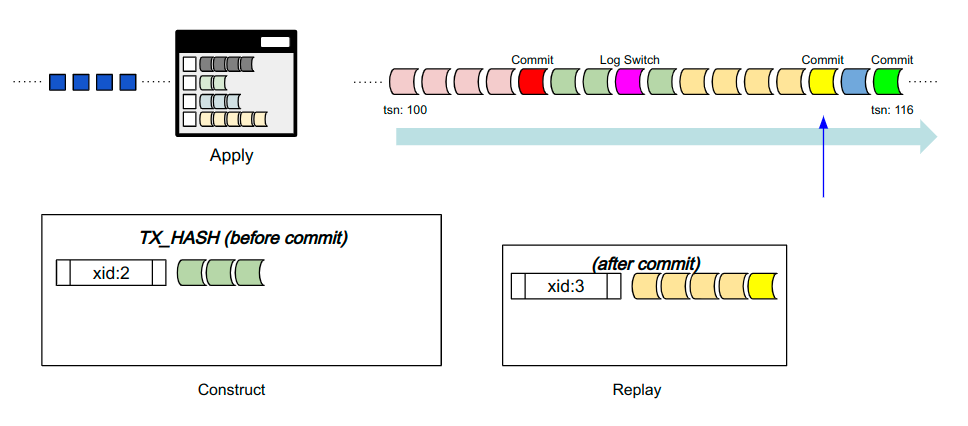
Replay Thread 는 `Commit` 레코드가 도달하여 Construct 로부터 조립이 완료된 트랜잭션을 전달 받는다. 전달 받은 트랜잭션은 `Commit` 레코드의 DB Time (Oracle의 SCN / Tibero의 TSN / .. )에 맞게 직렬화되어 반영되거나, 트랜잭션 내 `레코드` 들의 의존성을 모두 체크하여 병렬로 처리되게 된다.
병렬로 처리하게 될 경우 Replay Thread 의 갯수가 많아지게 되며, 각 쓰레드가 DB의 한 세션을 담당하게 된다. 병렬 처리 가능여부는 Control Thread 에서 실시간으로 판단하며, 병렬 처리가 가능할 때 여러 Replay Thread 에 일감을 부여하게 된다.
그림 3. Replay로 넘어간 트랜잭션
### Worker Threads
#### Resource Thread
프로세스의 `CPU` / `Memory` 사용량을 실시간으로 수집한다. 수집된 내용은 로그상에 계속해서 남겨주게 되며, 프로싱크 매니저와 연동 중일 경우, `Agent` 프로세스를 통해 수집한 값을 프로싱크 매니저로 전송한다.
#### Stat Thread
프로세스에서 발생하는 `트랜잭션` 의 시간당 처리량, 일종의 Throughput 을 계산한다. 프로싱크 매니저와 연동 중일 경우, `Agent` 프로세스를 통해 수집한 값을 프로싱크 매니저로 전송한다.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.
Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:
```
GET https://docs.tibero.com/prosync/4.5_manual/administration/apply/apply-process.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.